OCR built onlyfor historians.
Bandit is an OCR platform built for Classical Chinese texts. What a researcher corrects becomes the model's knowledge, so the next page is read better than the last.
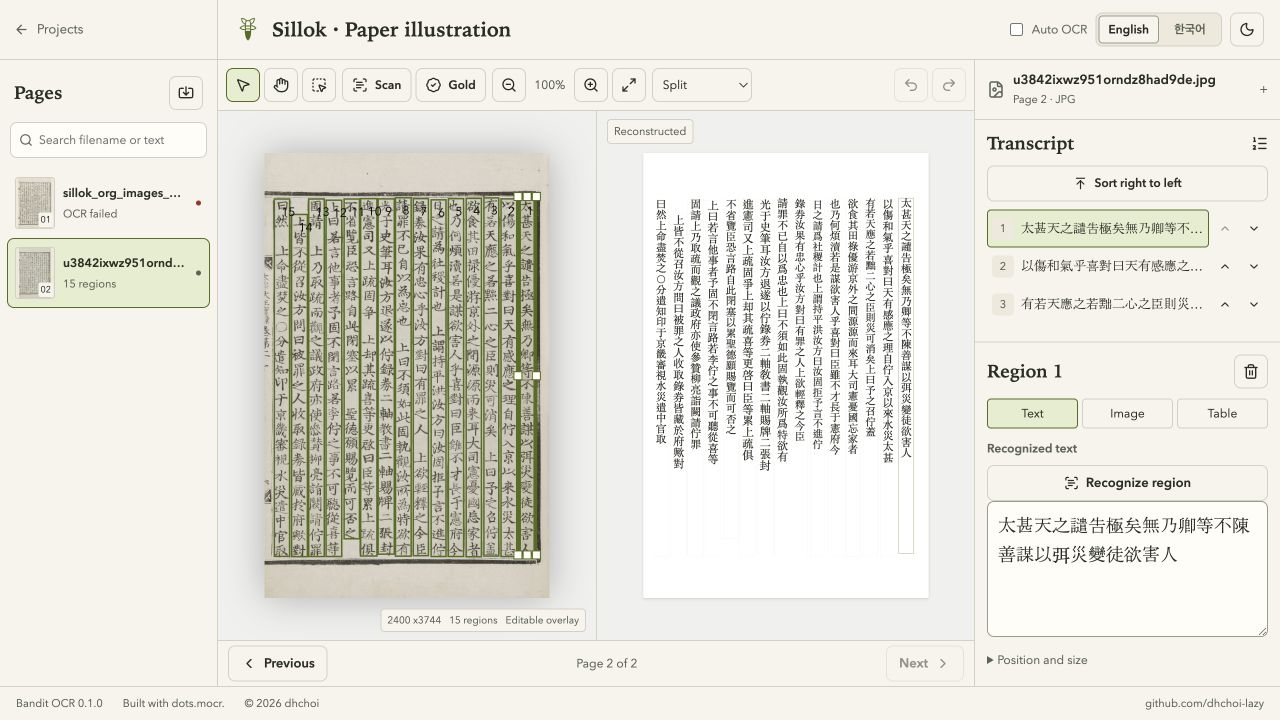
Built for the pages that ordinary OCR gives up on.
Feature 1. Built for Classical Chinese texts
Vertical columns, interlinear notes, worn type, dozens of columns to a page. Trained so far on premodern Korean sources; the coverage widens with each release.
Feature 2. Runs on your own computer
Recognition runs on your GPU and nothing is uploaded. Unpublished sources and personal records never leave the machine.
Feature 3. Gets smarter as you work
Mark corrected pages Gold and train the model on them. Your corrections become a personal adapter that the next recognition already uses.
Feature 4. Export that is ready to use
JSON, JSONL, CSV, Markdown, or a bundle of the whole project, saved wherever you choose.
From a scan to a reviewed text.
Import
Open page images or a PDF as a local project. PDFs are rasterized on your machine.
Recognize
Run one page or the whole project. Boxes appear as each column is read, and the editor stays responsive.
Correct
Move a box, fix a character, reorder columns, undo. Mark a page Gold when it is right.
Export
JSON, JSONL, CSV, Markdown, or a bundle of the project, from a normal save dialog.
What it needs to run
- Mac
- Apple silicon (M1 or later), macOS 14 or later
- Memory
- 16 GB minimum. 32 GB or more runs the model at full precision.
- Disk
- About 7 GB: the app plus the OCR model, downloaded once
- Windows
- Not yet built. NVIDIA GPU with CUDA planned.
- Network
- Only for the one-time model download
Download
Download